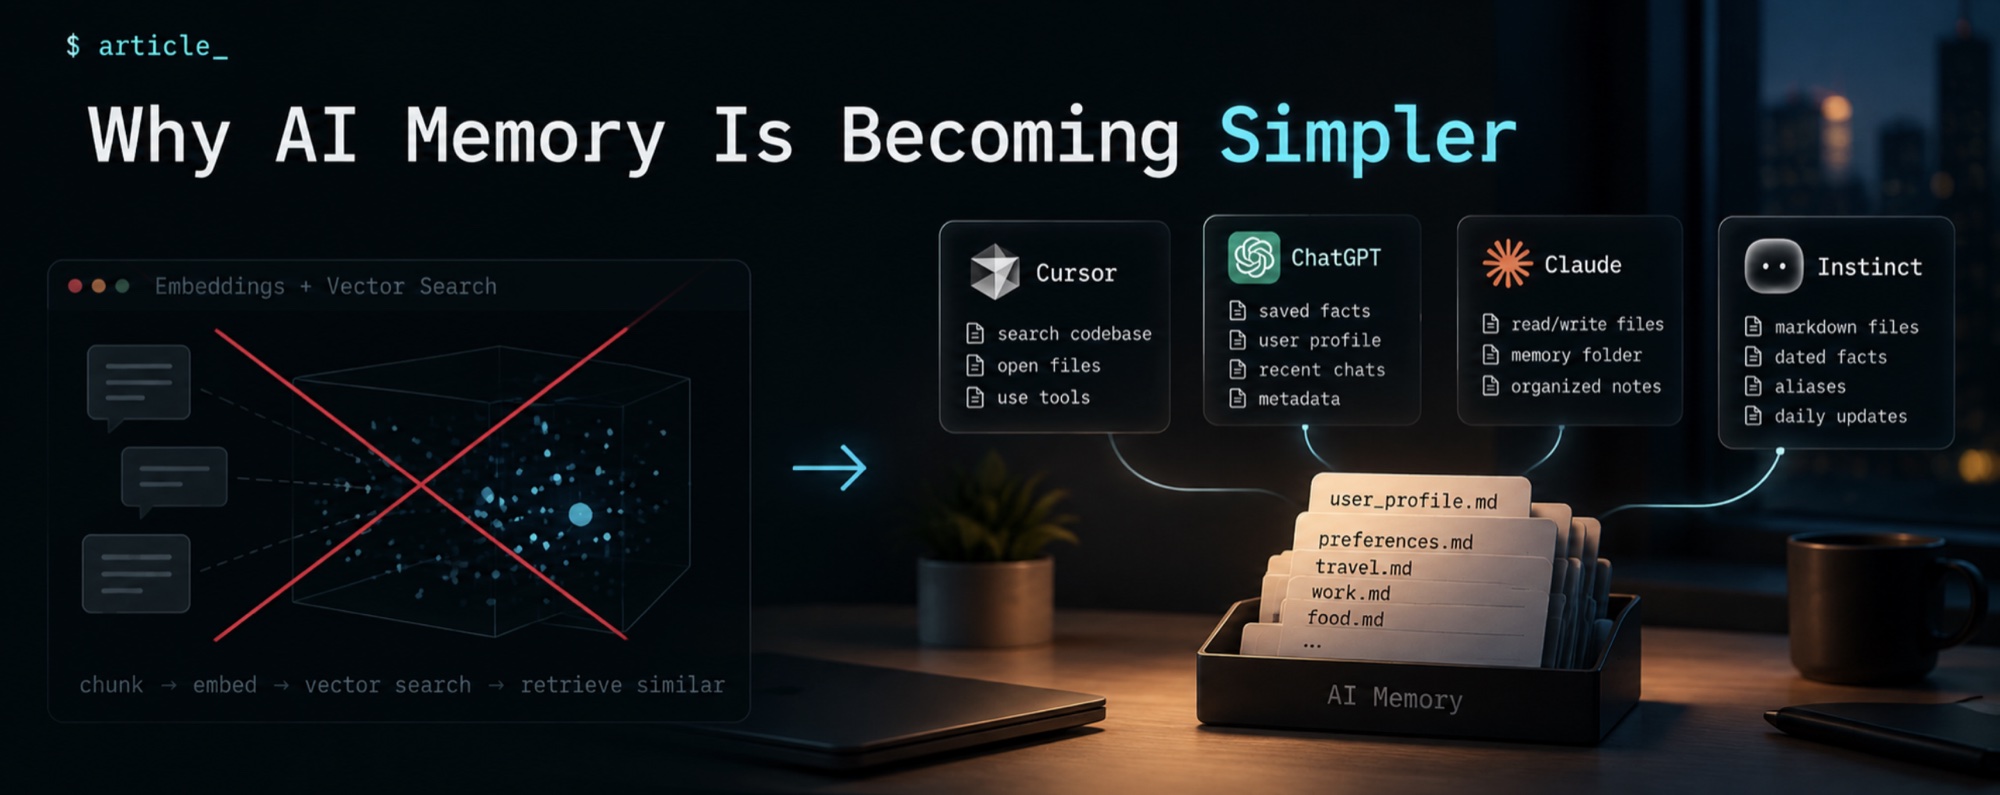
The best AI assistants of 2026 remember you by keeping notes and reading them back, not by searching for similar text. That's the opposite of what most memory products sell.
Two years ago the standard answer to "how should an agent remember?" was embeddings. You chop past conversations into pieces, turn each piece into a vector, and when a question comes in, you fetch the pieces that look most similar. Whole companies were built on this. But look at what the leading products actually do now, and almost none of them work that way.
01 What the products do
Start with Cursor. It used to index your codebase with embeddings so its agent could find relevant code. This year it stopped. Its reasoning, as discussed on Hacker News, was that agents had become good enough to search a repo directly, with grep and by opening files. What's interesting is that Cursor had reported a 12.5% accuracy gain from that index in January. So the index wasn't useless. It just wasn't worth what it cost to keep fresh.
ChatGPT went the same way. People who reverse-engineered its memory found no vector search over past chats at all. Instead, every message carries a bundle: facts you asked it to save, an AI-written profile of you, your recent conversations with timestamps, and some usage metadata. It doesn't pick what's relevant. It includes everything and trusts the model to ignore the rest. That bet has a nickname, the bitter lesson: stronger models make clever retrieval unnecessary.
Anthropic took a third path that ends up in the same place. Claude's memory tool lets the model read and write files in a memory folder. It finds things the way it finds code, by browsing and searching text. Anthropic says its newer models keep better-organised memories this way.
02 What Instinct does
Then there's Instinct, the iMessage assistant everyone has been trying lately. Dhravya Shah reverse-engineered its memory by questioning it, and his write-up is the most detailed account we have. Instinct stores memory as Markdown files tracked in git. Each file has a type, a list of dated facts, links to related files, and a line of aliases, like "food, lunch, restaurants" on a dining file. The aliases exist because the agent searches with plain keyword matching. There's no vector index and no BM25 ranking.
Two details of his account are worth noticing. First, the agent can only read memory. A separate job rewrites the files about once a day. It merges duplicates, turns examples into general traits, and replaces wrong facts with dated corrections. Second, every turn starts with a profile of about 4,000 tokens, including a section on when you want the assistant to act and when to ask. So again: a summary up front, files underneath, and grep to dig.
One caution. Shah founded Supermemory, a memory company, and his article ends by explaining how to rebuild Instinct with his product. He also never saw Instinct's code. His findings are probably mostly right, and he says some may be wrong. But it's a vendor reading a competitor.
03 Vendor benchmarks
That caution matters more than it seems, because most memory benchmarks come from vendors. Mem0's paper reports Mem0 beating plain retrieval by about 10%. Zep's paper reports Zep beating full-context answers by up to 18%. Mem0's blog now claims 92.5% on the LoCoMo benchmark. Each company tested its own product, chose its own setup and won. That doesn't make the numbers false. It makes them advertising until someone else reproduces them.
04 What independent research found
The most useful study is LongMemEval, from 2024. It tested how well assistants remember a user across many sessions. ChatGPT, given exactly the right past conversation, answered 92% of questions correctly. Relying on its own memory, it got 58%. Long-context models fed the whole history lost 30 to 55 points compared with being handed just the right evidence. A bigger context window didn't fix memory.
MemoryAgentBench, from 2025, compared every approach it could find. Plain keyword search held its own against embeddings at finding facts. Long-context models did better at understanding a long history as a whole. And one result stood out: every method, without exception, failed at updating facts that had changed. On multi-step updates, the best score was 28%.
A 2026 study called "When Does Memory Help?" tested agents doing real tasks where a fact gets introduced, later changed, then needed. Keeping one current version of each fact and overwriting it succeeded 75% to 100% of the time. Embedding retrieval got 30% to 70%, and swung by up to 45 points between identical runs. Mixing the two did worse than the fact store alone. Two more findings should worry anyone building this. Agents ignored correct facts sitting in their prompt about half the time. And changing only how facts were extracted moved results by up to 60 points.
Add the older "Lost in the Middle" result, which found that models miss information placed in the middle of long prompts, and a pattern appears.
05 Memory is a writing problem
Memory clearly helps. Without it, tasks that needed an earlier fact failed every time in that 2026 study. But the hard part was never search. It's writing: deciding what to keep, overwriting what changed, and forgetting what's no longer true. That's where every independent study found failure, and it's what vendor benchmarks measure least.
That explains why the products converged. When your memory is small and you control how it's written, you don't need clever retrieval. You need careful notes, a summary the model always sees, and a way to dig deeper when the summary isn't enough. Embeddings still earn their place when the history is too big to read, like a year of chats or a whole codebase. Even then, the research says to filter by date and keep keyword search alongside.
The industry spent two years treating memory as a search problem. The evidence says it was a writing problem all along.